
WHITEPAPER · APRIL 2026
The Measurement Gap.
A Framework for AI Code Observability in the Enterprise
For CTOs, VPs of Engineering, and CIOs accountable for AI investment outcomes.
- 93.9%frontier AI beats human developers (SWE-bench)
- 42%of all code is now AI-generated
- 0%of orgs can attribute AI code per agent
Section 1
Executive Summary
42% of all shipped code is now AI-generated[1]. The latest frontier models already score 93.9% on SWE-bench Verified — outperforming human developers at resolving real-world production bugs[2]. Yet virtually no organization can tell you which agent wrote which line, or whether that code survived a week in production. The gap is not the technology — it is the absence of observability.
Standard engineering intelligence platforms (DX, LinearB, Faros) measure team-level activity: cycle time, deployment frequency, PR velocity. None of them measure what fraction of a commit was authored by AI, which agent produced it, or whether that code survives in production.
Without per-line attribution, three critical questions remain unanswered:
This paper proposes a measurement framework based on three KPIs (Adoption, Durability, Churn) and an open standard (git-ai v3.0.0) for capturing per-line AI attribution at commit time. The approach is local-first, vendor-portable, and compatible with existing engineering intelligence tools.
How much of our shipped code is AI-generated?
Does that code survive — or does it generate rework?
Which vendors and teams use AI most effectively?
Section 2
The State of AI Coding in 2026
AI coding is no longer a pilot program — it is production infrastructure. 42% of all code is now AI-generated[3]. Frontier models outperform human developers on real-world bug resolution. The question is no longer "should we use AI?" but "which AI, and how do we prove it?"
- 93.9% — SWE-bench Verified — frontier AI vs 67–70% human baseline[4]
- 90% — of the Fortune 100 have deployed GitHub Copilot[5]
- 3–4x — productivity gains at Goldman Sachs with agentic AI coding[6]
- 42% — of all code is now AI-generated or AI-assisted[3]
- 280K — developer hours saved by Morgan Stanley's DevGen.AI in 5 months[7]
- $7.6B — AI code tools market in 2025 — projected $26B by 2030[8]
Section 2b
Enterprise Adoption by Sector
AI coding tools are no longer experimental pilots. They are production infrastructure at the world's largest organizations. 90% of the Fortune 100 have deployed GitHub Copilot alone[9]. But adoption depth varies dramatically by sector.
Sources: GitHub Blog, JetBrains 2025, public filings, GOV.UK AICA trial
| Sector | Adoption |
|---|---|
| Fortune 100 | 90% |
| Technology / SaaS | 85% |
| Banking | 78% |
| Government | 45% |
| All developers | 82% |
Section 2c
What the Analysts Say
Every major analyst firm has published on AI in software engineering. The consensus: adoption is inevitable, but measurement and governance are lagging dangerously behind.
Adoption trajectory and market size projections
- 14%Enterprise engineers — using AI (Gartner) (2024)
- 82%Developers use AI — weekly (JetBrains) (2026)
- 90%Gartner prediction: — enterprise adoption (2028)
- 80%Smaller, AI-augmented — teams (Gartner) (2030)
- $7.6BAI code tools — market (2025)
- $26BProjected market — (2030, 27% CAGR)
- $91BProjected market — (2035, Precedence)
Sources: Gartner, Grand View Research, Precedence Research, JetBrains 2025
The Productivity Paradox (DORA 2025)
INDIVIDUAL METRICS (UP)
- +21%tasks completed
- +42%code is AI-generated
- +98%PRs merged
- 30–60%time saved coding
ORG METRICS (FLAT / DOWN)
- 0%delivery improvement
- 4xcode duplication
- −7.2%delivery stability
- 2xcode churn (projected 2026)
Sources: DORA Report 2025, Sonar Developer Survey, ByteIota 2026 analysis
Section 2d
The Regulatory Imperative
Regulatory pressure is converging on AI-generated code from three directions: the EU AI Act, financial compliance (SOX/SOC 2), and emerging code quality mandates. Organizations that cannot identify which code was AI-generated will face audit findings, compliance gaps, and procurement blockers within 18 months.
EU AI Act enforcement timeline
YOU ARE HERE
- February 2025February 2025 — Prohibited practices — EU AI Act
- August 2025August 2025 — GPAI model rules — apply
- August 2026August 2026 — Full enforcement — Transparency + marking
- August 2027August 2027 — High-risk systems — full compliance
Section 3
The Measurement Gap
Engineering organizations have invested in measurement platforms for over a decade. DORA metrics, SPACE framework, DXI scores. None of them measure AI authorship.
Only 16.8% of organizations track investment per AI tool versus benefit[8]. Of the remaining 83.2%, most rely on developer surveys, anecdotal feedback, or no measurement at all. When the board asks if the AI budget is paying off, the honest answer is "we don't know."
| Platform category | What it tracks | Measures AI? |
|---|---|---|
| Engineering intelligence (DX, LinearB, Faros) | Cycle time, throughput, PR velocity, DORA | No |
| Code quality (SonarQube, Code Climate) | Static analysis, test coverage, complexity | No |
| AI gateways (LLM proxies) | Token consumption, API cost | Inputs only |
| Developer surveys | Self-reported satisfaction | Subjective |
| AI code observability (Iria Monitor, git-ai) | Per-line attribution, durability, churn | Yes |
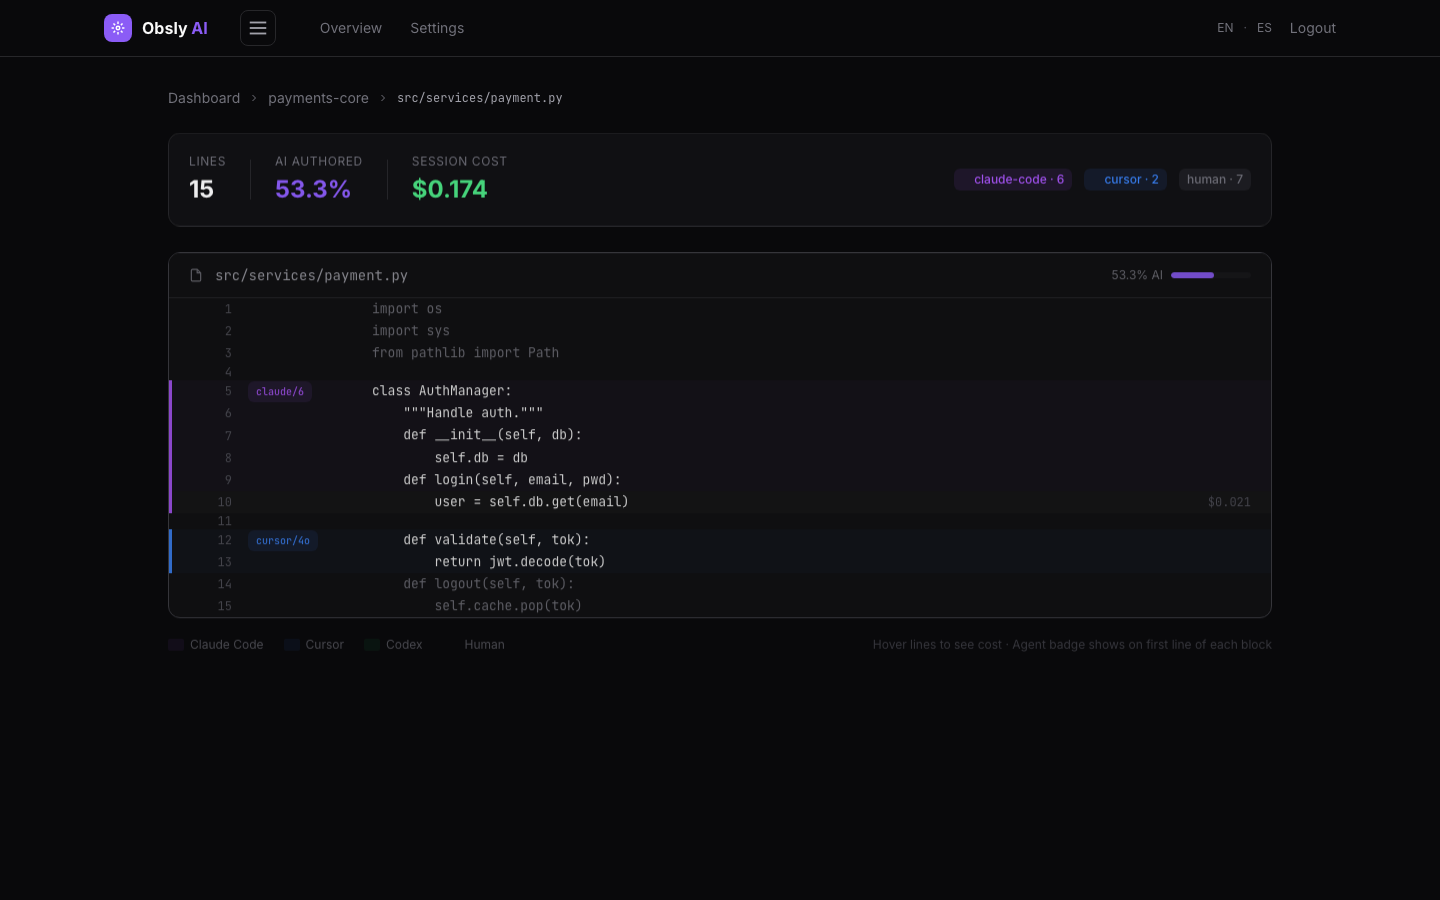
The gap is not in the data — git already stores everything needed. The gap is in capturing AI authorship at the moment of creation, before the signal disappears.
Section 4
A Framework for AI Code Observability
The framework is built on three principles:
PreToolUse and PostToolUse hooks when they edit files. Capturing the diff at this moment is deterministic. Detection after the fact (e.g., AI classifiers on diffs) achieves <60% accuracy.refs/notes/ai as structured git notes following the open git-ai v3.0.0 standard. The data travels with the code, survives rebases via post-rewrite hooks, and is accessible to any tool that reads git.- DEVELOPER'S MACHINE
- AI agents
- Claude Code · Cursor
- Codex · Windsurf
- hooks
- iria-monitor CLI
- computes diff
- attributes lines
- refs/notes/ai
- git-ai v3.0.0
- open standard
- git push (metadata only, no source)
- IRIA MONITOR CLOUD · OPTIONAL
- Aggregation
- · Per vendor
- · Per repository
- · Per developer (private)
- KPIs
- Adoption
- Durability
- Churn
- Export
- PDF · CSV · BI
Section 5
Three KPIs That Matter
Per-line attribution is the foundation, but the value comes from three derived metrics. These are the numbers a CTO should be able to recite for any quarter, repository, or vendor.
Adoption = (lines AI-attributed) / (total lines added) × 100Adoption alone is not a quality metric. A vendor at 80% AI may be performing better or worse than one at 30%. The value of Adoption is contextual: it sets the denominator for the other two KPIs.
Industry benchmark: Healthy teams operate between 25–40%. Above 40%, rework rates increase 20–25%[7].
Durability(30d) = (AI lines unchanged 30 days later) / (AI lines added) × 100The single most important metric. Durability separates valuable AI code from rework. A line that survives 30 days in production was worth generating. A line rewritten the same week was not — it consumed prompt tokens, review time, and trust.
Why it matters: Two vendors at 70% Adoption can have wildly different outcomes. One at 90% Durability is delivering value. One at 55% is generating rework you pay for twice.
Churn(7d) = (AI lines rewritten by human within 7 days) / (AI lines added) × 100Churn is the inverse signal of Durability and the leading indicator of trouble. High churn means humans are systematically correcting AI output. It points to wrong tool choice, wrong prompts, or wrong domain fit.
Diagnostic value: Churn segmented by agent reveals whether the issue is the tool (Cursor 18% vs Claude 6% on the same repo) or the developer (one team 4%, another team 22% on the same agent).
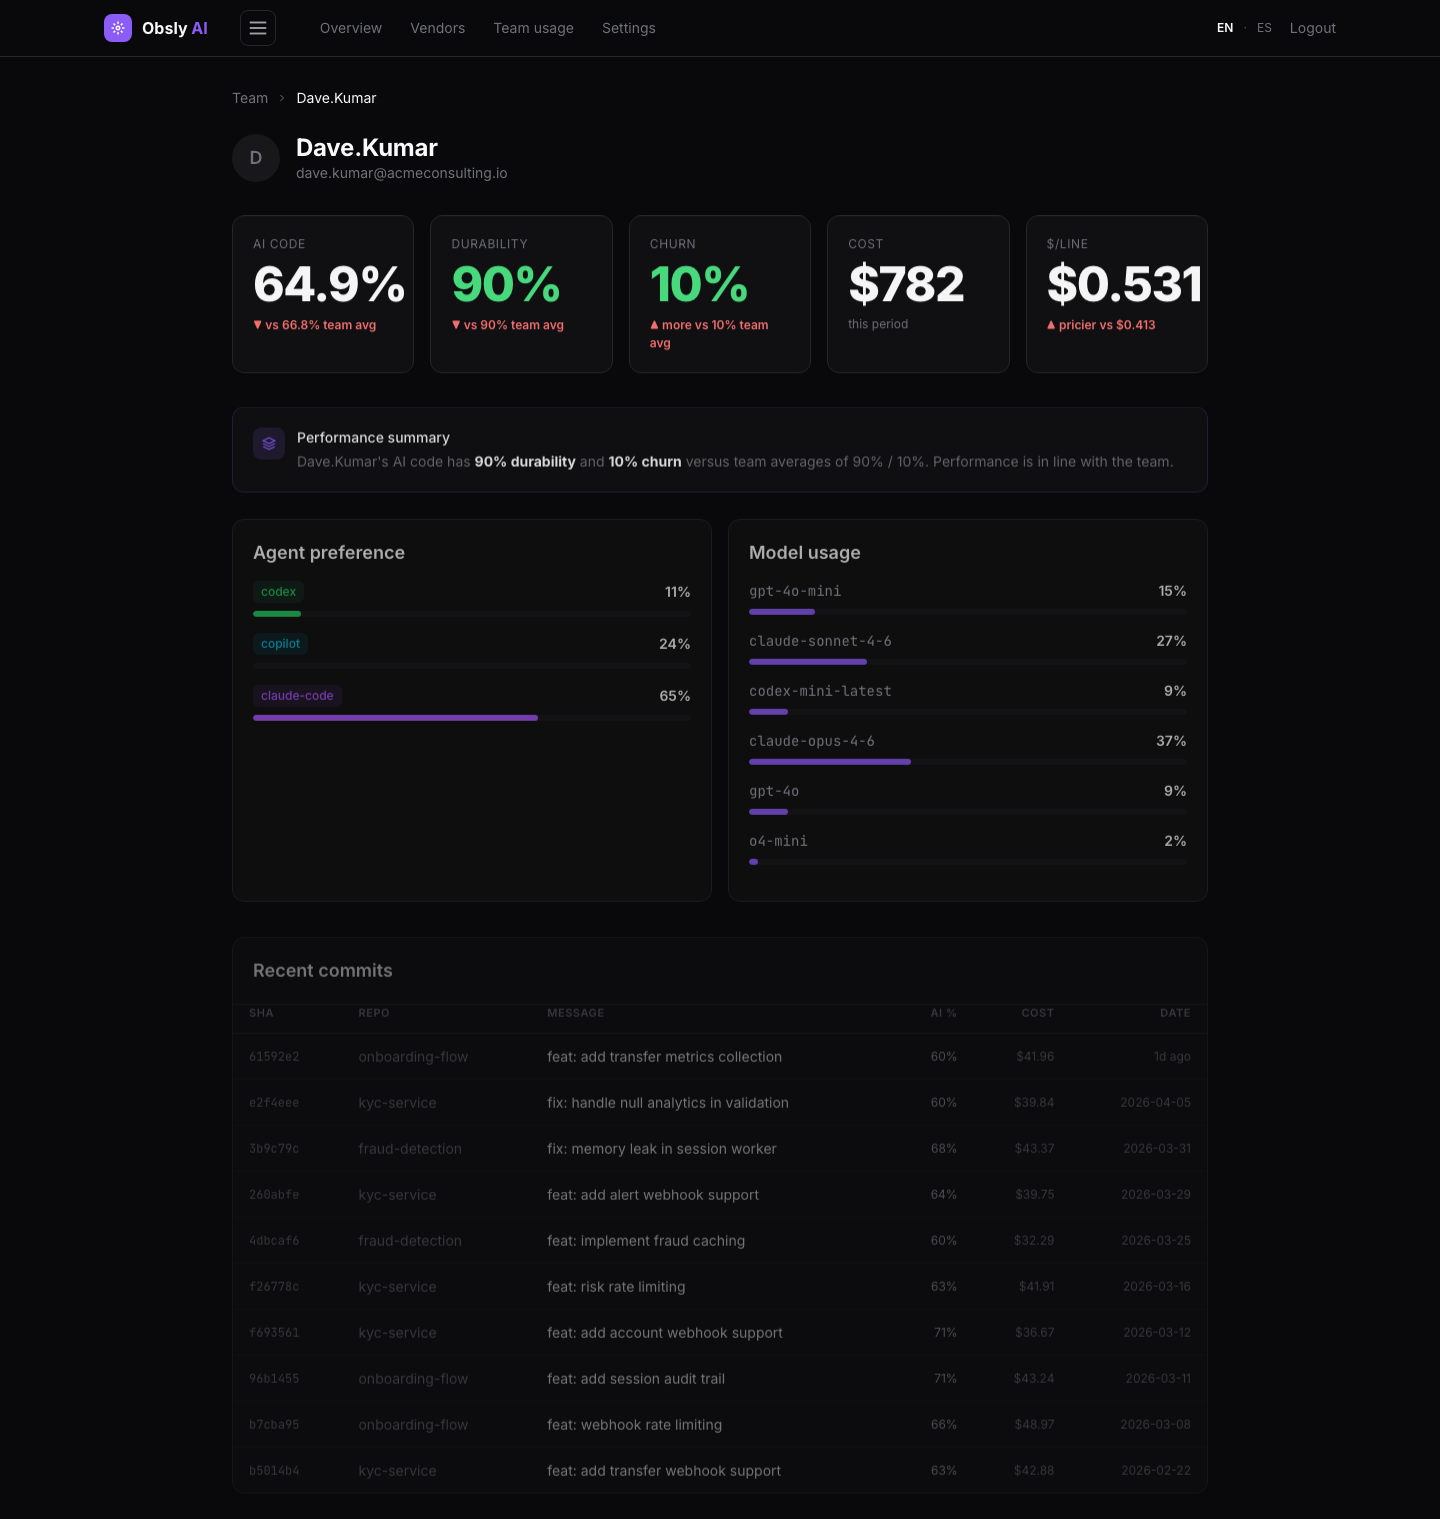
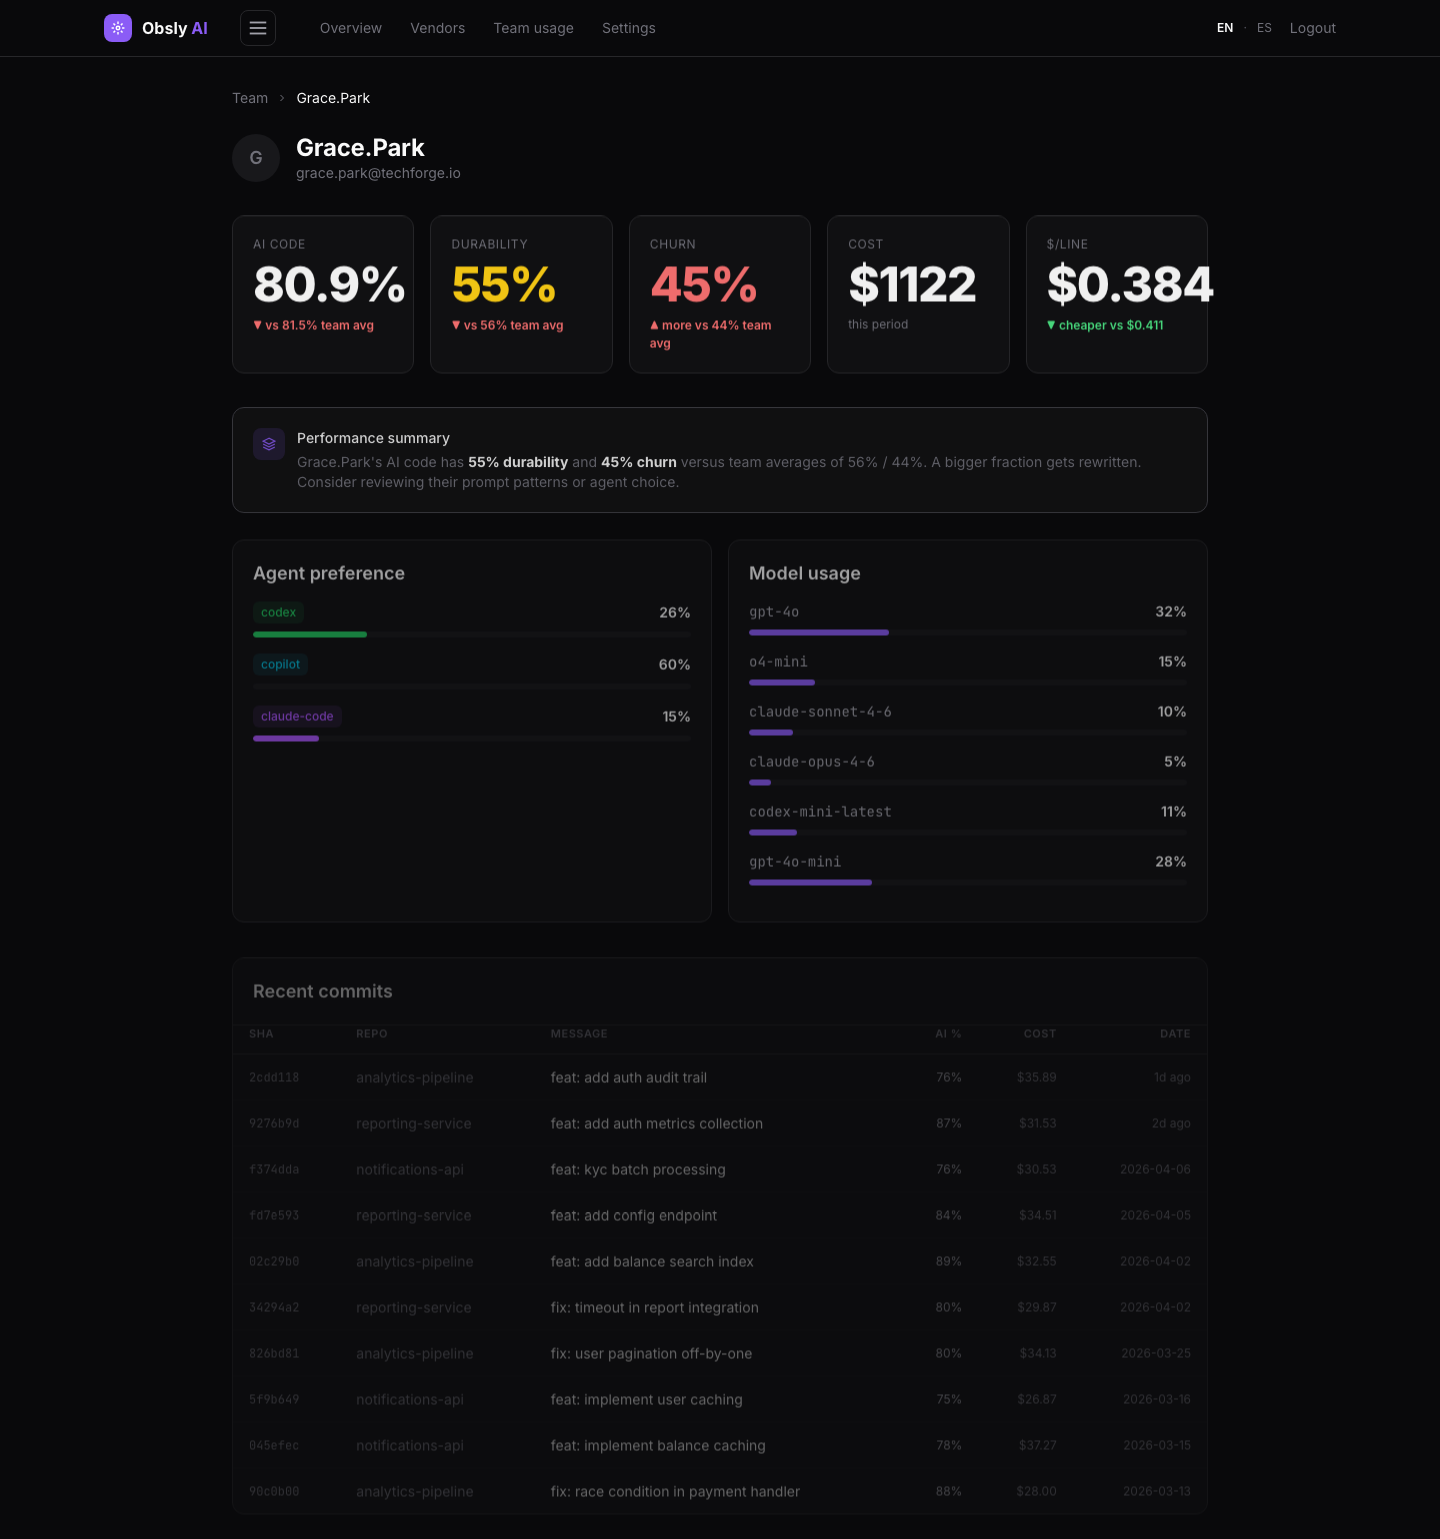
Figure 2: Same enterprise, two vendors, different outcomes (IriaBank demo data)
Section 6
Implementation Path
AI code observability does not require a new SDLC. It is a layer added to existing repositories without disturbing developer workflow.
- Week 1 — Pilot on a single repositoryInstall the CLI on three engineers' machines. Confirm hooks fire on every commit. Validate git notes appear under
refs/notes/ai. - Week 2 — Connect the dashboardInstall the GitHub App. Verify that pushed commits appear with their attribution. Establish baseline Adoption / Durability / Churn for the pilot repo.
- Weeks 3–4 — Roll out to one teamOnboard a complete engineering team. Compare per-developer metrics privately. Identify high-Durability and high-Churn patterns for coaching.
- Month 2 — Vendor visibilityFor organizations with external vendors, invite them as data providers. Establish quarterly review cadence with KPIs as agenda.
- Quarter 1 — Board-ready reportFirst quarterly report with three numbers: Adoption, Durability, Churn. Trend line. Vendor comparison. The report your CFO has been asking for.
Section 7
Illustrative Scenario
The following scenario is illustrative and based on patterns observed in 2026 industry research. Names are anonymized.
A European retail bank engages two consultancies to deliver a new mobile banking platform. Both vendors charge equivalent rates per developer. After Q1, the bank's procurement team requests AI code attribution data from both vendors.
| Vendor | Adoption | Durability (30d) | Churn (7d) |
|---|---|---|---|
| Vendor A | 68% | 91% | 4% |
| Vendor B | 82% | 58% | 23% |
The reading: Vendor B uses AI more aggressively (82% vs 68%) but produces code that gets rewritten almost a quarter of the time. The bank pays for both the original generation and the rework. Vendor A uses AI less but with substantially better outcomes.
The conversation that follows: The bank does not need to terminate Vendor B. With this data, they can ask specific questions: which agents are being used, on which file types, by which teams. The data turns a vague concern into a structured procurement discussion.
Section 8
Conclusion
AI coding tools are not the problem. The absence of measurement is. Enterprise budgets have grown faster than the instruments to evaluate their return.
The framework proposed in this paper is intentionally minimal: three KPIs, one open standard, no source code transmission. It complements rather than replaces existing engineering intelligence platforms. It produces numbers a CTO can take to a board meeting and a procurement team can take to a vendor review.
The companies that adopt this layer in 2026 will be the ones that can answer, in twelve months, the only question that matters: did the AI investment pay off?
Appendix
The Open Standard
Iria Monitor implements the git-ai v3.0.0 specification, an open standard for AI code attribution stored as git notes under refs/notes/ai. The format is human-readable, version-controlled, and portable across tools.
Organizations adopting the standard retain full data portability. If a tool change is required for any reason, the underlying attribution data is independent of the analytics platform reading it. This is the same principle that made OpenTelemetry the default for observability instrumentation: the data outlives the vendor.
For the technical specification, see github.com/git-ai-project/git-ai.
References
Sources
- [1] Sonar Developer Survey 2026 & NetCorp, AI-Generated Code Statistics 2026. 42% of all code is now AI-generated or AI-assisted.
- [2] Anthropic, Claude Mythos Preview, April 2026. 93.9% SWE-bench Verified; human developer baseline 67–70%.
- [3] Sonar Developer Survey 2026 & NetCorp, AI-Generated Code Statistics 2026. 42% of all code is now AI-generated or AI-assisted.
- [4] Anthropic, Claude Mythos Preview, April 2026. 93.9% SWE-bench Verified; human developer baseline 67–70%. MindStudio benchmark analysis.
- [5] GitHub Blog, Research: Quantifying GitHub Copilot's Impact with Accenture, 2025. 50,000-developer deployment. 90% Fortune 100 adoption per Satya Nadella, July 2025.
- [6] Lucidate, Goldman Sachs Scales AI Coding to Thousands of Agents, 2026. 12,000 developers, 3–4x productivity with Devin autonomous engineer.
- [7] Entrepreneur, Morgan Stanley Created an AI Tool That Saves Developers 280,000 Hours. DevGen.AI processed 9M lines of code across 15,000 developers in 5 months.
- [8] Grand View Research & Precedence Research. AI code tools market: $7.65B (2025), projected $26B (2030, 27% CAGR), $91B (2035).
- [9] GitHub Blog, Research: Quantifying GitHub Copilot's impact in the enterprise with Accenture, 2025. 50,000-developer deployment; 84% more successful builds.
- [10] TechResearchOnline, Anthropic Enterprise AI Adoption Gains Momentum in 2026. Salesforce 90% Cursor adoption; Microsoft Claude Code adoption.
- [11] AIX Network, Case Study: JPMorgan Chase AI. 200,000+ LLM Suite users, $2B investment, 40–50% productivity in operations.
- [12] Lucidate, Goldman Sachs Scales AI Coding to Thousands of Agents, 2026. 12,000 developers, 3–4x productivity gains with Devin.
- [13] Entrepreneur, Morgan Stanley Created an AI Tool That Saves Developers 280,000 Hours. DevGen.AI, 9M lines of code in 5 months.
- [14] Banking Dive, Citi eyes AI productivity gains. 30,000 developers, 9% productivity lift via Google Cloud Vertex AI.
- [15] DefenseScoop, DOD initiates large-scale rollout of commercial AI models, December 2025. GenAI.mil: 3 million users.
- [16] DefenseScoop, DOD wants AI-enabled coding tools for developer workforce, February 2026. FedRAMP High + IL5 requirements.
- [17] GOV.UK, AI coding assistant trial: UK public sector findings report, 2025. 50 organizations, 56 min/day saved, 58% would not go back.
- [18] Gartner, 80% of Governments Will Deploy AI Agents by 2028, March 2026.
- [19] European Commission, EU AI Act. Full application August 2, 2026. Transparency obligations + high-risk system compliance from August 2027.
- [20] Virtuoso, Testing AI Generated Code in Regulated Industries, 2025. 29–48% AI code security weaknesses; SOX/PCI DSS implications.
- [21] Baker Tilly, Evolving SOC 2 reports for AI controls, 2026. CC9.2 tied to AI model integrity; 80% of audit outcomes depend on evidence quality.
- [22] Veracode, GenAI Code Security Report, 2025. AI code has 2.74x more vulnerabilities. 100+ LLMs tested across 4 languages.
- [23] CodeRabbit, 2025 was the year of AI speed. 2026 will be the year of AI quality. 1.7x more issues in AI-authored PRs (470 PRs analyzed).
- [24] Anthropic, Claude Mythos Preview, April 2026. 93.9% SWE-bench Verified (human baseline 67–70%). MindStudio, Claude Mythos Benchmark Results.
- [25] Anthropic, Project Glasswing: Securing critical software for the AI era, April 2026. 27-year OpenBSD vulnerability, 16-year FFmpeg flaw surviving 5M test runs. $100M in credits committed.
Build your measurement layer.
Iria Monitor is the reference implementation of the framework described in this paper. Free for individual developers. Per-seat for teams. Custom for enterprise.
See the personal coach
Take the same framework down to the individual loop — local, leading, no ranking.